
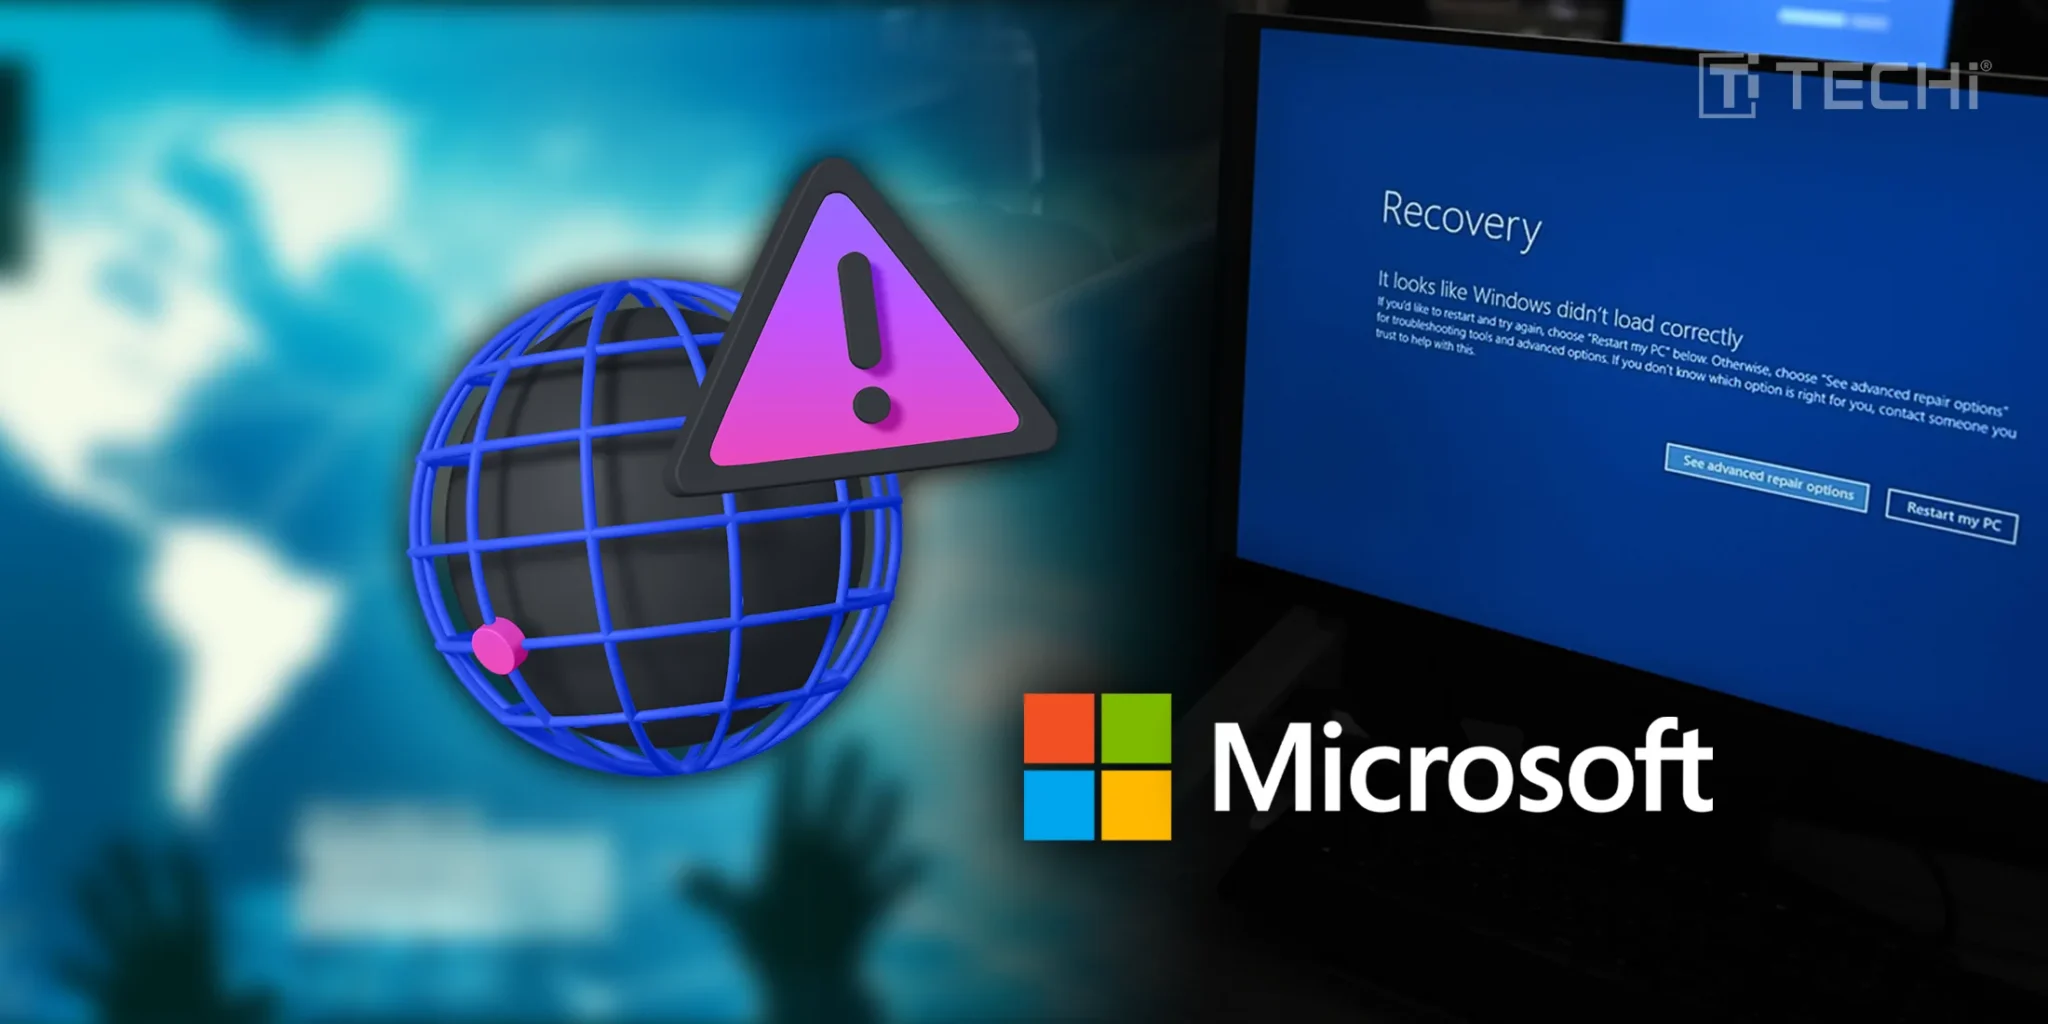
Most of the sites and apps knocked offline by Wednesday's Microsoft Azure failure were back by Thursday morning. The outage ran about eight and a half hours, took down large parts of Microsoft 365 and Xbox along with hundreds of unrelated customer websites, and traced back to a single configuration change that Microsoft's own safety checks failed to stop.
What actually broke
The failure sat in Azure Front Door, Microsoft's global edge network. AFD accepts traffic at points of presence around the world and routes it to whatever sits behind — it is the front door for the Azure Portal, for Microsoft 365 sign-in, and for thousands of customer sites that have no visible connection to Microsoft at all.
Microsoft's incident record puts the start at 15:41 UTC on 29 October and full mitigation at 00:05 UTC on 30 October: eight hours and 24 minutes. Because the break was at the edge, requests failed before they ever reached the applications behind it. That is why so many services went from working to completely unreachable with nothing in between.
Early advisories pointed at DNS, and Microsoft briefly told customers to stop managing AFD through the web portal and use PowerShell or the CLI instead. Microsoft's own account of the cause landed somewhere else. An inadvertent tenant configuration change spread across the AFD fleet; the protection mechanism that should have rejected an inconsistent config did not fire, because of a software defect in that protection path. Edge nodes then failed to load their configuration properly, and the failure widened as more of them picked it up.
Who felt it
The blast radius was wide because AFD sits in front of so much unrelated business.
In the UK, Heathrow's website went down, NatWest and Royal Bank of Scotland customers lost online banking, and Asda, BT and O2 all took hits. The Scottish Parliament suspended voting entirely — the Presiding Officer told MSPs the electronic voting system was unusable, and business at Holyrood stopped until it came back.
In the US, Alaska Airlines and Hawaiian lost their websites and online check-in. The airline told passengers to see an agent at the airport for a boarding pass and to allow extra time in the lobby, then stood up backup infrastructure and had booking and check-in working again that afternoon. It was Alaska's third significant IT failure in three months. Starbucks, Kroger and Costco customers hit problems with mobile ordering, loyalty and point-of-sale.
Microsoft's own estate was not spared: Microsoft 365, Outlook, Teams, the Azure Portal, Copilot, Xbox Live and Minecraft were all degraded or down. Downdetector logged more than 20,000 reports at the peak, shortly after noon US Eastern.
The fix took longer than finding the cause
Microsoft identified the problem quickly. Undoing it was the slow part. The company blocked further customer configuration changes to AFD, rolled the service back to the last known good configuration, then brought nodes back progressively while rebalancing traffic through the points of presence that were still healthy.
Staged recovery across a global edge fleet is deliberately unhurried — pushing everything back at once risks a second failure on top of the first, and a fleet of edge nodes coming back simultaneously can overwhelm the origins behind them. It is also the reason users saw a long tail of slow pages and delayed mail after the headline services were nominally restored.
The concentration problem, nine days after the last one
This was the second major cloud failure in under a fortnight. Amazon Web Services had its own multi-hour incident on 20 October that took out a comparable spread of consumer services.
Dr Saqib Kakvi of the Department of Information Security at Royal Holloway, University of London, made the structural point on the day: Amazon, Microsoft and Google hold "an effective triopoly on cloud services," so an outage in part of one provider's infrastructure can cripple hundreds or thousands of applications at once. Azure alone accounts for roughly a fifth of global cloud infrastructure spending, per Synergy Research Group.
The economics push in one direction. Running your own edge network is expensive and hiring people to operate it is harder. Buying AFD, or CloudFront, or Cloud CDN, is cheap and fast. The cost of that trade shows up on days like Wednesday, and it is paid by the customers of firms that never chose Azure and have never heard of it.
No attack, no breach
Nothing about this was hostile. Microsoft attributed it to a configuration change from the start, and there has been no indication of unauthorised access or data exposure. Sign-in failures during the window were the edge refusing traffic, not accounts being locked or credentials being compromised — the authentication systems were fine, users just could not reach them.
The more valid complaint was about visibility. The Azure status page was itself degraded for part of the incident, which pushed Microsoft to post updates on X. A status system that depends on the infrastructure it reports on has an obvious flaw, and IT teams said so loudly.
Awkward timing
The outage landed on the same day Microsoft reported quarterly results. Revenue came in at $77.7 billion, up 18%, with Azure and other cloud services growing 39% — a strong quarter by any reading, delivered while a chunk of that same cloud was unreachable. The stock slipped anyway, on capital-spending guidance rather than the outage.
What to take from it
Microsoft said it would keep customer configuration changes to AFD restricted while it deployed additional safeguards, and pointed to faster automated rollback as the fix that matters — a system that reverts itself to a known good state in minutes rather than requiring an engineer-led recovery measured in hours.
For everyone else, the practical lesson is narrower than "don't use the cloud." It is worth knowing which single vendor service sits in front of your traffic, whether you can route around it, and how long it takes to do that under pressure. Most of the businesses that spent Wednesday afternoon offline could not answer the third question.
About the Author
Hafsa Rizwan is a seasoned writer and proofreading editor at TECHi, where she leads a team of writers to deliver impactful technology coverage. She reports on the stories behind the tech headlines, providing deep analysis on all tech product-related news, industry giants, new product ecosystems, and app innovations. As an Architect and technology journalist, her expertise is uniquely focused on the critical shifts transforming how we connect, create, and build, a focus exemplified by her coverage of the fascinating intersection of architecture and technology.

Comments